Presenting the Data
Challenge
Dealer listings become more useful when collectors can search and compare them in one place. The application needs to retain the original source and show the limits of the available data.

Django Application
I build and maintain Milivault’s Django site, hosted on Render with PostgreSQL on AWS RDS and images in S3. The public site provides catalog search, category browsing, dealer pages and research content.
On October 13, 2026, its homepage displayed 531,639 tracked listings, including 178,729 marked available, from 147 dealers. These are displayed catalog counters, including the archive, rather than an independent data-quality audit.
Accounts and collection-related workflows are part of the project. Features under development or private testing are described separately from public functionality.

Selecting a Conflict. Here we select World War One.

Selecting a nation. Here we select Hungary.
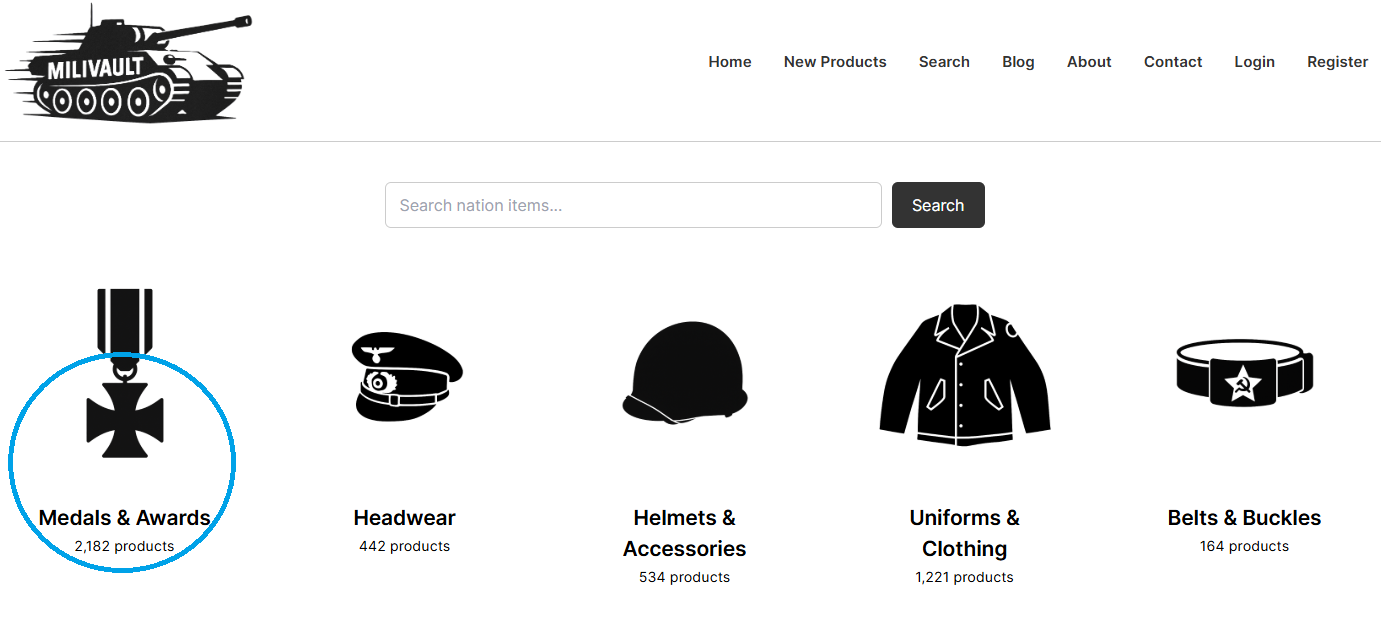
Finally we select a item type. Here we select Medals & Awards.
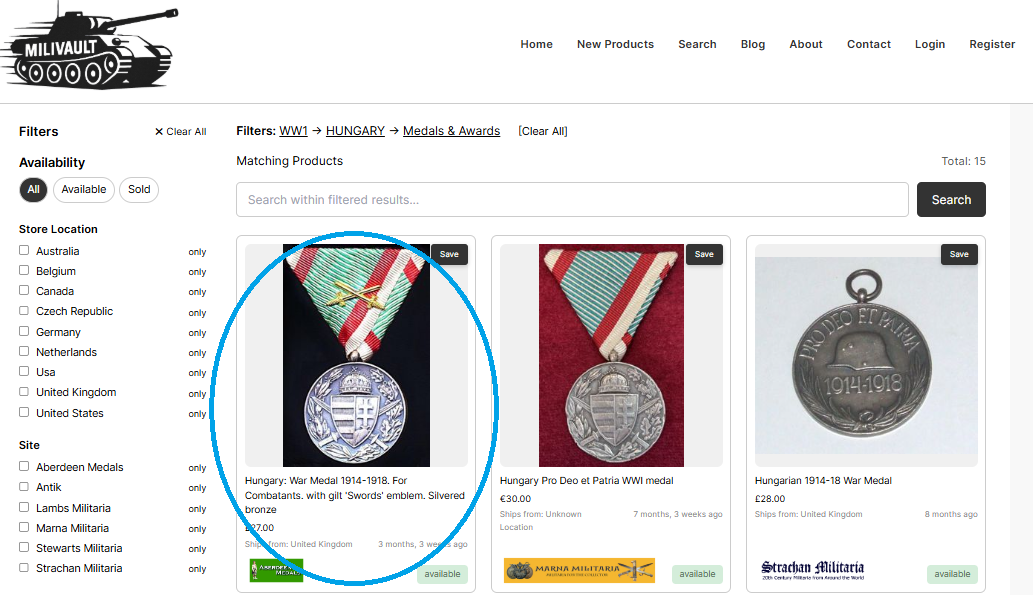
Now you can see all the products that fall into the categories you selected. We will select the first product.
Reading a Product Page
The examples show a dealer listing with its title, asking price, source, description, images and structured classification fields.
Availability reflects Milivault’s observations and the source’s reported status. Currency displays and layouts may have changed since these screenshots.
The original dealer link remains essential: confirm current price, availability and item details with the source before acting on a record.

Internal Review Tools
Earlier Streamlit prototypes supported batch labeling and exploratory SQL queries. The screenshots below document that historical work.
Django is now the canonical direction for classification review. Internal and local tools support operational work, but their presence in the project does not mean every feature is publicly released.
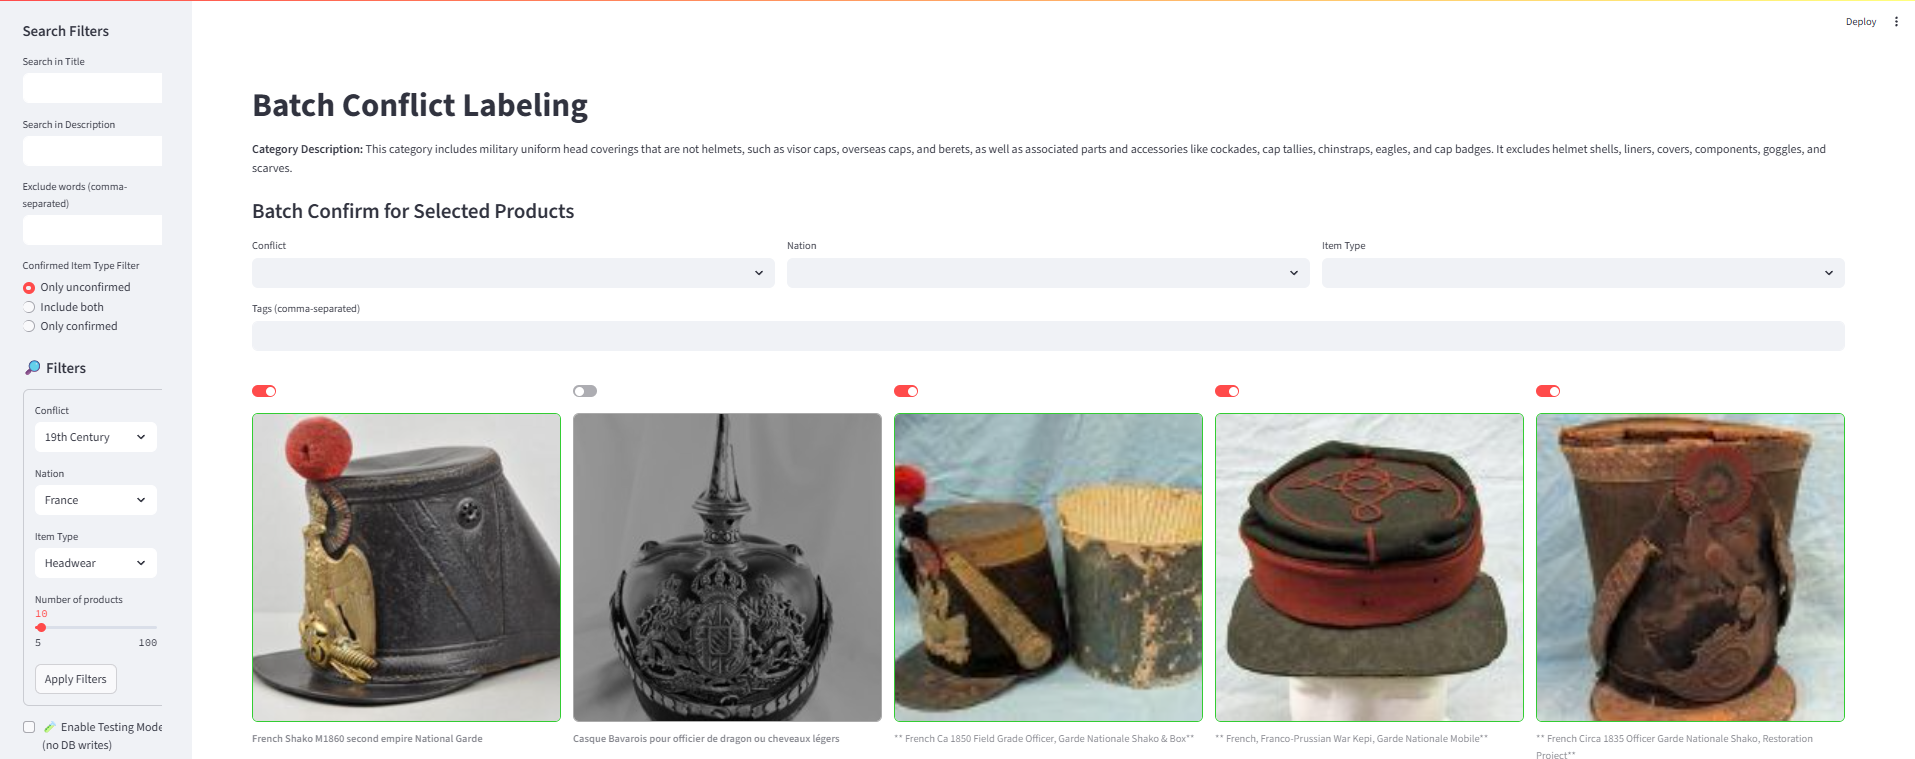
Historical Streamlit batch-review example: selecting records to confirm a category while leaving an apparent mismatch for investigation. Human review supports label correction; this screenshot does not measure catalog-wide classification accuracy.
What the Project Demonstrates
A working path from Python collection and cleaning through PostgreSQL storage to a Django search application.
Practical integration of scikit-learn experiments, OpenAI-assisted classification and human review.
Ownership of source configuration, troubleshooting, application development and deployment, with extensive Codex assistance and manual verification.
Testing and Iteration
In my September 2026 update, I described testing the private Precise Watch workflow with safe test data: creating a watch, checking email on desktop and mobile, following dealer links, giving relevance feedback and checking unsubscribe settings.
That process exposed confusing navigation and email settings that I revised and tested again. The post described Precise Watch as private testing, rather than a public release.

My Responsibilities
I am Milivault’s founder and solo developer. I handle Python scraping and ingestion, the PostgreSQL data layer, the Django application, classification work and deployment.
I use Codex extensively alongside manual work and troubleshooting. The platform is portfolio evidence of practical delivery and maintenance; it does not imply years of paid engineering employment or independently verified performance benchmarks.
Current Development Direction
My October 2026 update focuses on reducing repeated collection work, improving classification routing and experimenting with finer-grained identification of German WWII medals.
Photo-based identification and comparable-price estimates remain ideas and experiments described in that post. Dealer asking prices are not confirmed sale prices, and estimates would not be definitive appraisals.