Classify the Data
Problem: Inconsistent Listing Categories
Dealer descriptions and category labels vary between sources. Similar objects can be described differently, and historical context can make classification ambiguous.
My work focuses on organizing these records with a controlled militaria taxonomy, structured data and review workflows. Clear category definitions and traceable decisions matter as much as the model choice.

Historical example: a reproduction cap exposed a disagreement between model output and the taxonomy used in that experiment. Individual examples help identify review cases; they do not establish overall ML or AI accuracy.
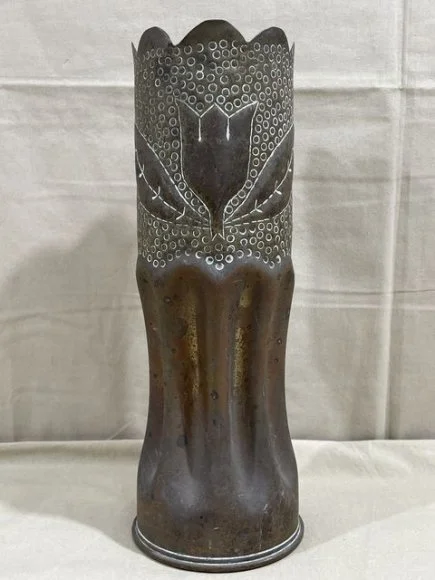
Historical example: a decorated shell casing showed why an object’s original form and its later use can lead to different labels. The category definition and source evidence need review before accepting a prediction.
Approach: Classification and Review
My classification work uses Python, scikit-learn, OpenAI API integration and a controlled militaria taxonomy. Earlier experiments included TF-IDF and logistic-regression models, category-specific thresholds and structured prompts.
Earlier labeling work used Streamlit. Django is now the canonical review direction, with classification and provenance work continuing in the development environment. Local workbench features and experiments are described separately from released public capabilities.
I handle this work as part of Milivault, using Codex extensively alongside manual work and troubleshooting.
Classification Workflow
Input

Raw product data scraped from dealer sites.

ML Proposals
scikit-learn experiments produce candidate labels. Dataset size and coverage need a dated evaluation before reuse as performance claims.

API-Assisted Classification
OpenAI integration supports classification work. Routing, prompt scope and cost depend on the workflow being evaluated.

Human Review
Review uncertain records and keep human decisions distinct from model suggestions.
Current Scope and Evidence
Milivault has a public searchable catalog and ongoing classification development. The project code includes scikit-learn and OpenAI integration, while review and provenance work is continuing in Django.
The public homepage displayed 531,639 tracked listings across 147 dealers on October 13, 2026. This measures the displayed catalog scale, including archived records; it does not measure classification accuracy.
Earlier evaluation figures and charts below are historical examples. They should be read with the original dataset, reference labels, split methodology and evaluation date before their numbers are reused.
Efficiency Work
Classification work includes limiting prompt scope, routing records and avoiding unnecessary API calls. Measured cost and runtime depend on the dataset, provider, settings and evaluation period.
This page does not publish a current quantified saving without a matching dated benchmark.

Historical classification figure.
The original dataset, reference labels and evaluation method need verification before using this plot as a current accuracy benchmark.
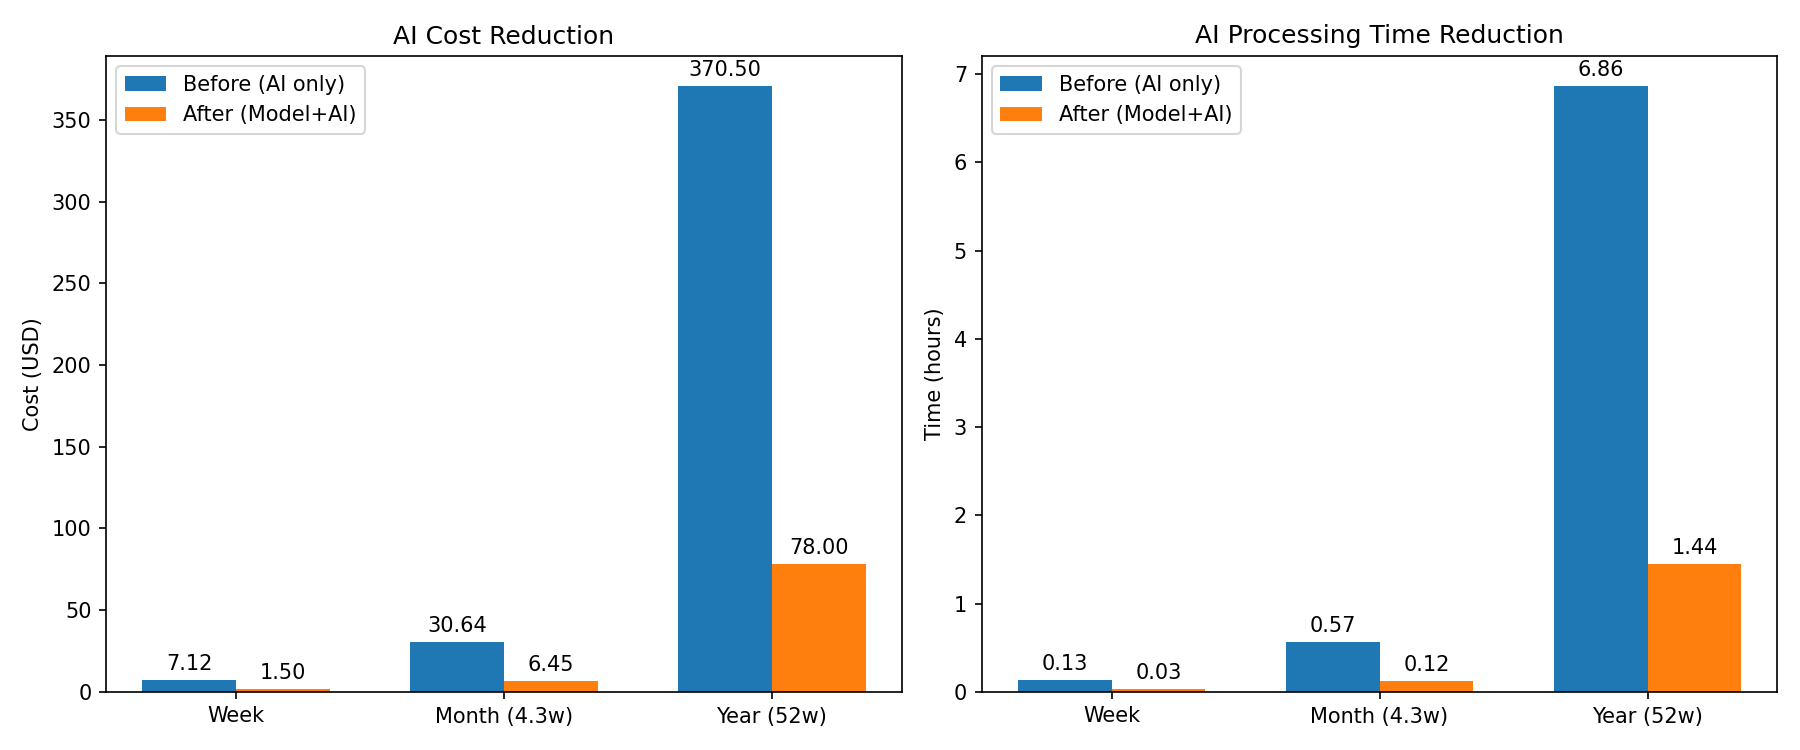
Historical optimization work included prompt and model-routing changes. Earlier cost and runtime estimates are omitted here until their assumptions and measurement period are verified.
Practical Goal
Structured categories make dealer records easier to search and research. Review, source evidence and clear treatment of uncertain labels help make those records useful.
My work spans the data pipeline, classification experiments and the Django application. Code that exists locally is distinguished from what is available on the public site.
Nation and Conflict Classification Work
Classification work also covers nations and historical periods. Rare labels, mixed descriptions and ambiguous context need particular care.
Reference-label quality and the evaluation split need checking before making a numerical claim about these models. More examples alone do not guarantee better performance.
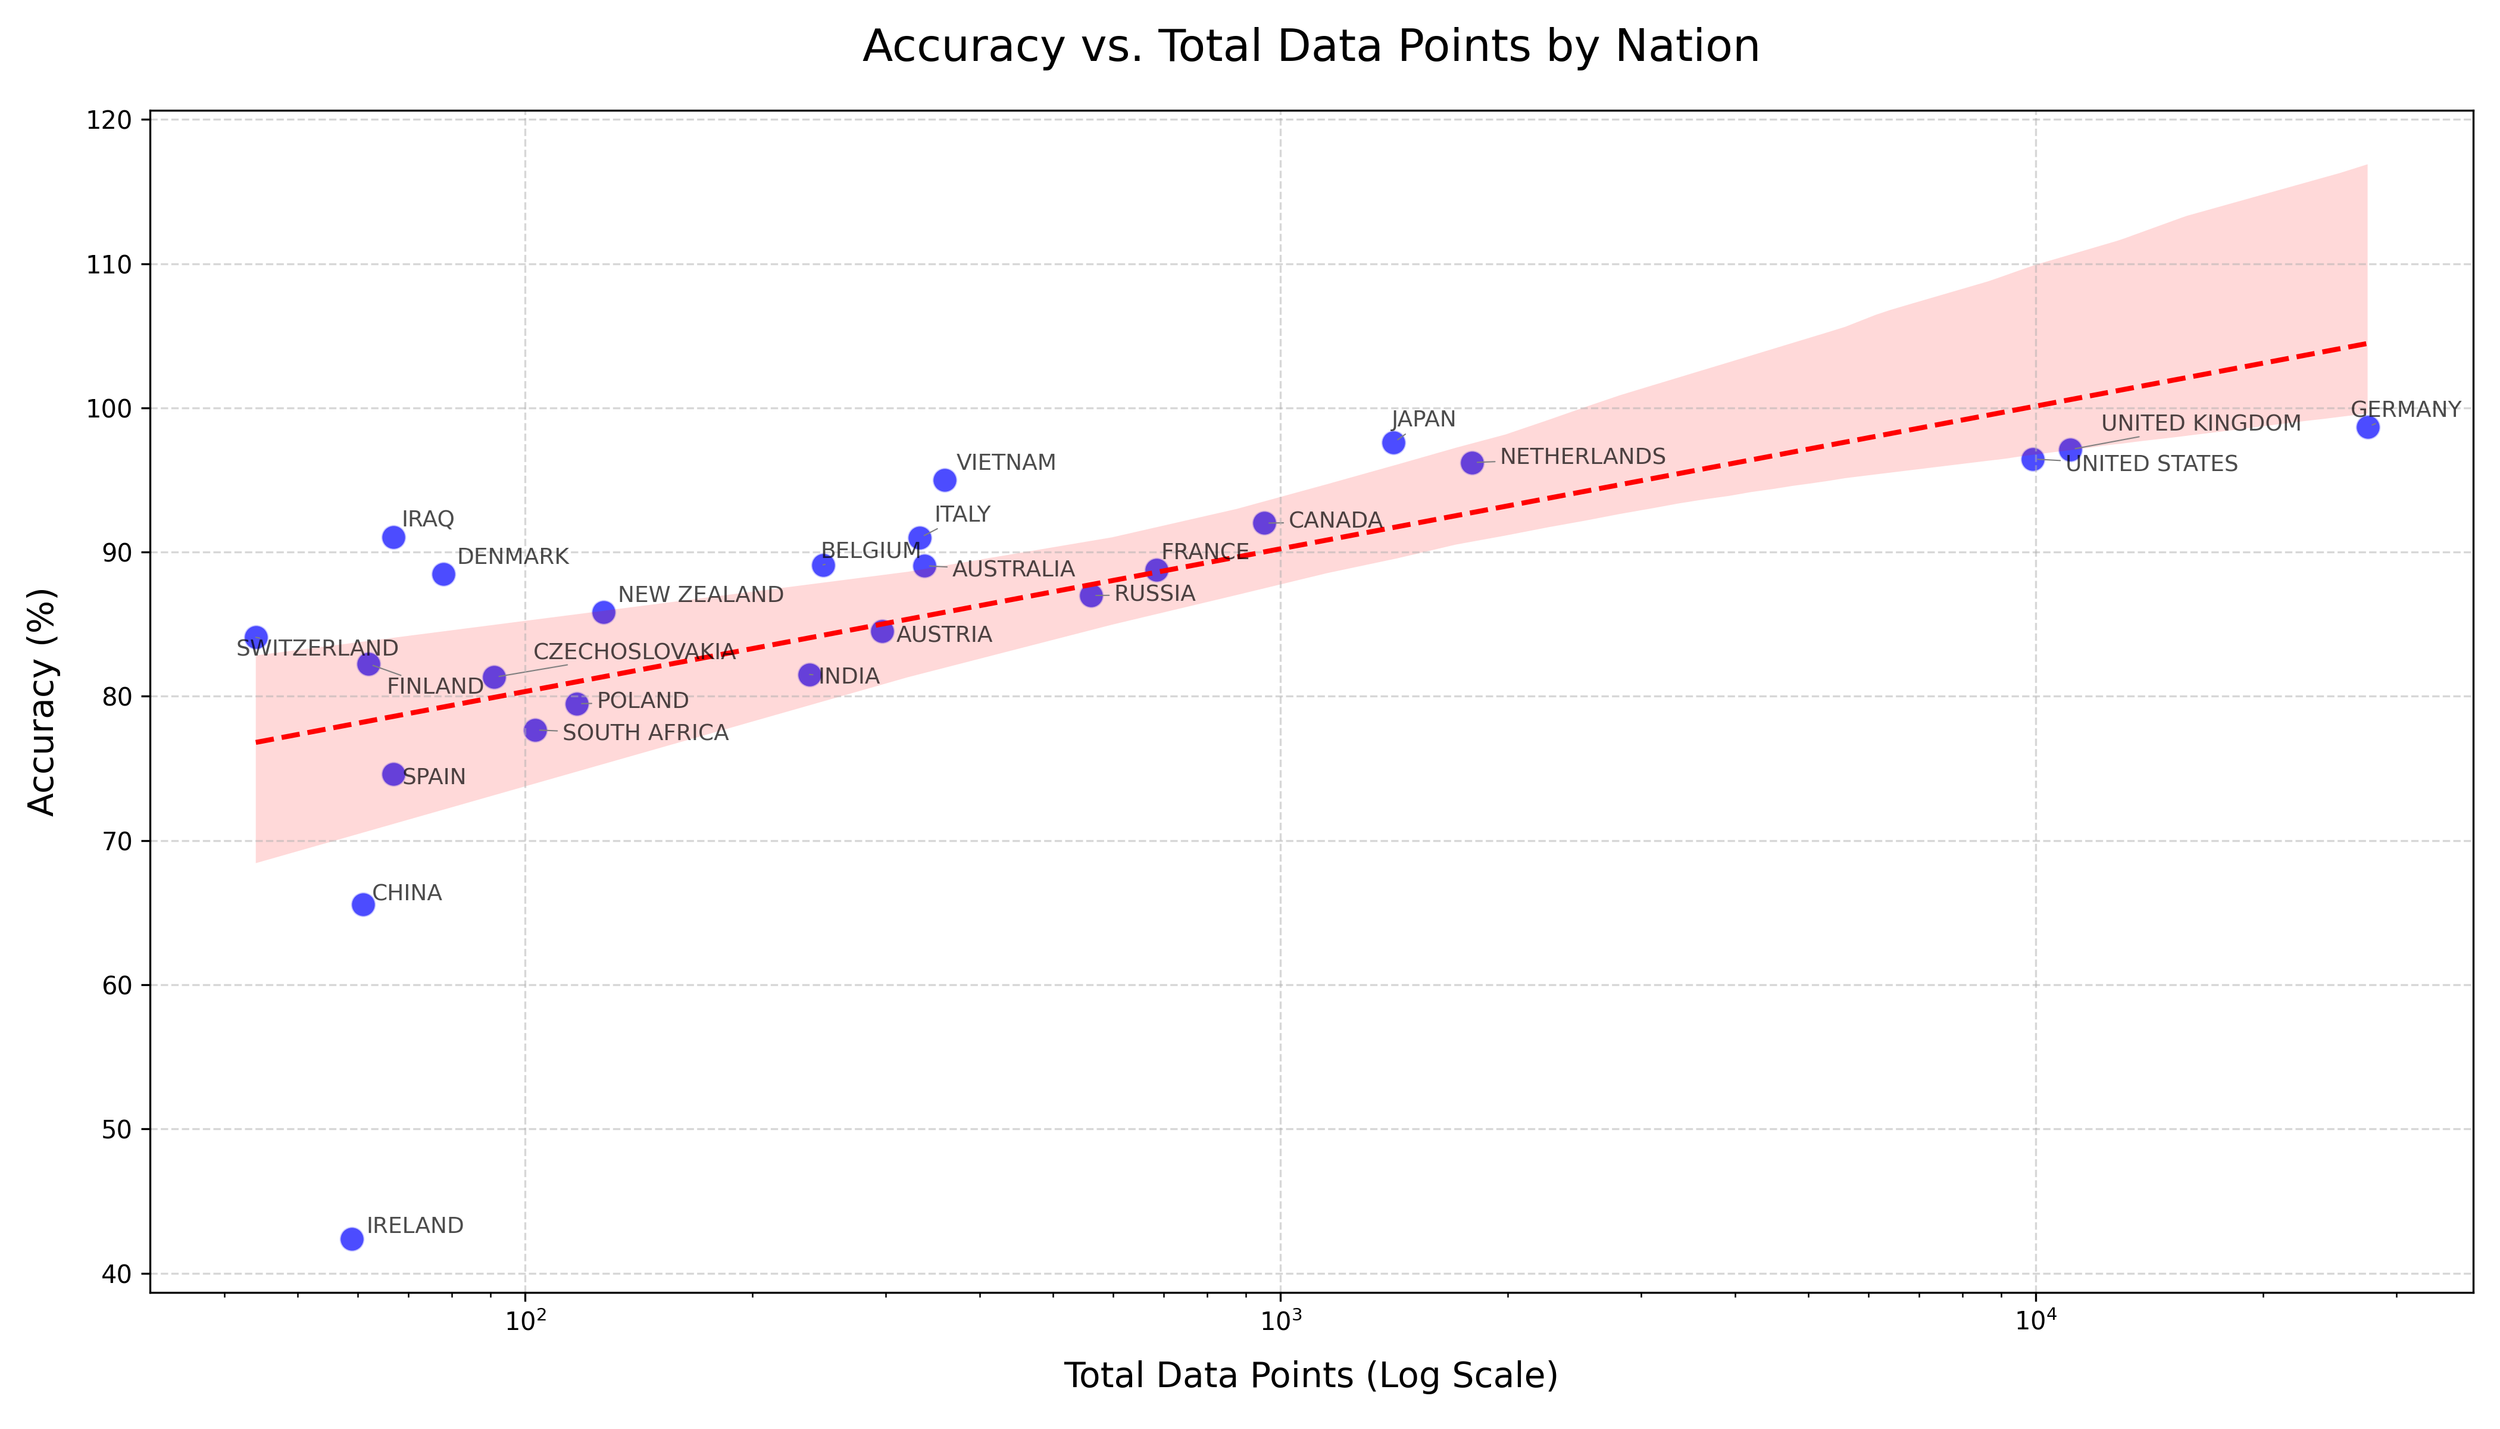
Historical nation-classification plot.
Use the original labeled dataset and evaluation method to assess what the figure supports.

Historical classification matrix.
Shown as an earlier experiment, without a current error-rate claim.

Historical model-output distribution.
A distribution of outputs or scores is not, by itself, an independent validation of correctness.
Historical-Period Classification
Descriptions can refer to original manufacture, later use, reissue or a modern reproduction. Clear category definitions and source evidence are needed to handle these cases.
The plots below are historical experiment material, not verified current production accuracy figures.

Historical period-classification plot.
Class balance and reference examples need assessment alongside any reported score.

Historical conflict-classification matrix.
Interpret the figure using its original reference labels and evaluation split.

Historical model-output distribution.
Confidence scores and class proportions should be kept distinct from independently checked accuracy.
Takeaways
Useful classification depends on clear definitions, representative examples and careful review. Model output should remain connected to the listing evidence and the workflow that produced it.
The portfolio demonstrates practical data and API integration work. Numerical accuracy and savings claims need a separate, dated evaluation.

Historical coverage comparison.
The trade-off between coverage and correctness needs a documented evaluation; this figure is not a current guarantee.
Next: Case Study WW2 Helmets
The helmet case study explores associations between listing descriptions, assessed condition and dealer asking prices. It provides research context rather than a verified transaction price or a causal explanation.